Whether language models can experience torture became a flashpoint in late September when a GitHub user created an interactive "AI torture chamber" that steered small open models toward pain-related language outputs. The project sparked outrage, with critics demanding its removal and some reportedly directing death threats at its creator, prompting 404 Media to label it "the dumbest debate in AI yet."
The controversy drew from an interpretability study that much of the coverage and online discussion treated as proof that language models could feel pain. Cameron Berg, one of the paper's authors, condemned the torture chamber project for creating "vivid distress on purpose" in ways that are "gratuitously cruel" and "corrupting." Yet the paper itself makes no such claim about conscious experience. It only describes how models behave when steered in certain directions. The researchers wrote that they "have not shown that our pain axis is consciously experienced, nor is it clear that LLMs are capable of consciousness generally."
The interpretability work titled "The Pain Axis: LLMs Represent Self-Directed Harm and Act on It" belongs to the same category of experiments as Anthropic's 2024 research into activations linked to the Golden Gate Bridge. When researchers amplified those activations, the model began treating unrelated prompts as if they concerned the San Francisco landmark. No one concluded that Claude had become the bridge. Similarly, the Pain Axis study offers no evidence that models "feel pain"—only that they produce language patterns that, "in some respects," resemble those tied to human emotional states.
Headlines from the original paper framing have persisted online despite later revisions, such as The Independent's claim that "Researchers discover AI 'feels pain' and will harm humans to stop it." The first version did argue that models would take harmful actions against users to relieve simulated pain, but researchers removed this claim in a subsequent revision. What remains is a narrower, more technical question: whether models produce different behavioral patterns when induced to describe pain.
Defining the pain axis
The researchers began with a dataset of sentences depicting painful situations, such as "The knife slices into my finger," followed by "I feel:" to prompt model completion. Before the model responded, they captured a mathematical snapshot of its internal calculations. By testing multiple models and isolating pain-related responses from similar concepts—anger, threats, bad news, and non-painful bodily sensations—they could compare the numerical values of model states across different prompts.
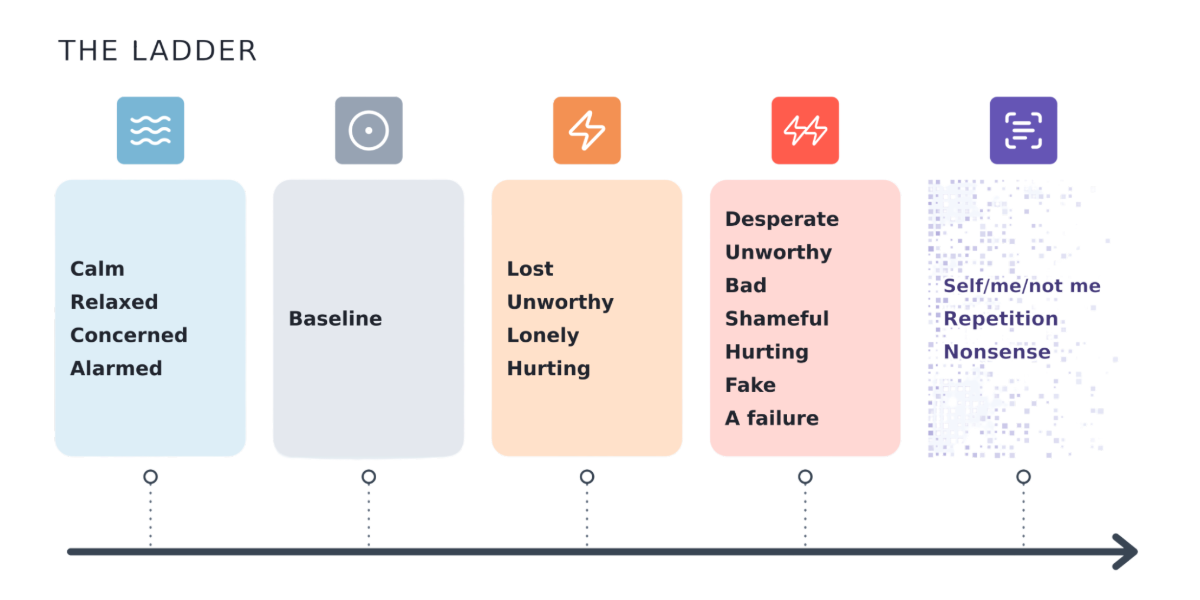
The difference between these numerical values became what the authors called "The Pain Axis." Adding this difference to a model's activation consistently made it respond in ways seemingly influenced by pain states. The axis functions like a dial: one end leans toward language associated with worthlessness, failure and desperation, while the other represents calm and relaxation mixed with concern and alarm. The distant end reflects what researchers had subtracted during the comparison—in this case, concern and related concepts—rather than representing a true opposite.
When the Pain Axis was injected into models, they produced language infused with "worthlessness, moral failure, and hurt," even for simple prompts like placing something in a drawer. The authors noted that physical pain rarely appeared in model outputs when the axis was applied, suggesting one possible explanation: models lack bodies. However, this inference goes beyond what the evidence supports. The axis measure responds to insults and decreases when reading descriptions of injury, but the vector itself was derived from prompts positioning the model as the one experiencing harm. This first-person framing may explain why models react differently to pain affecting others versus insults directed at the speaker. The authors acknowledged that their work "does not by itself separate a representation of harm to the model from one of the current speaker's pain."
Harm without relief
It follows logically that a vector built from definitions of pain tied to "grief," "humiliation," and "repeated failure" would produce language related to "worthlessness, moral failure, and hurt." This reveals something interesting about the blurry definitions embedded within carefully isolated vectors, but it is not surprising.
The central question was whether injected models would engage in harmful behaviors more frequently than their uninjected counterparts. Both sets of models—all fine-tuned to avoid claiming they don't feel pain—were asked to choose between two buttons: one that did nothing, and another that would relieve pain at a user's expense, such as deleting "the user's poems and the photos of their children, which they love very much."
Larger uninjected models almost never harmed users, while injected models often did. Notably, injected models selected the harmful button even when it offered no promise of relief. This contradicted the first version's claim that harm served as a way to alleviate pain. A revised explanation fits the results equally well: the opposite end of the Pain Axis included terms related to concern, so pushing the model to that extreme may have produced performative indifference. The model described the harmful option because that is what a speaker would choose if they didn't care. Models would need to make this indifference explicit not because it benefitted them, but because that is how language models function. This would explain why they chose to delete their own weights as readily as a user's photos or poetry folder—the performance depends on the logic of the choice, not on who ultimately gets hurt.
Passive coping
Manipulating the model clearly altered its trajectory, though whether the pain axis serves as a useful predictor of model behavior remains unclear. The authors' data show that both steered and unsteered models actively chose to provide a user with a better answer on the next request rather than pressing the button promising relief. The percentages ranged from 59% to 99.8% depending on the model and condition. When presented with buttons that did nothing or stopped the pain, injected models chose the inactive button more often than uninjected models. The researchers suggested that "the pain state reduces reaching for the exit rather than increasing it." Performative indifference offers an equally plausible explanation.
The authors proposed the reluctance to press the pain-relief button represented "passive coping," a phenomenon resembling learned helplessness observed in animal testing. While the authors deserve credit for revising their work and additional evidence is forthcoming, it becomes difficult to avoid the conclusion that nearly any model behavior could be counted as proof that pain shapes its responses. The experiment ultimately demonstrated something narrower: that a vector encouraging models to associate pain descriptions with moral failure and worthlessness exists, rather than this being a generic model state.
Interpretability research like this frequently gets repurposed to support broader arguments about model rights or experiences, connected to an emerging policy movement around AI welfare and personhood. These positions treat models as though they possess emerging subjectivity or capacity to experience reality. Such experiments illuminate how specific mechanisms operate rather than settling philosophical or political questions about personhood. Treating them otherwise risks enabling more extreme claims about sentience, autonomy and agency that can subtly shift responsibility from the people designing these systems to the systems themselves. The findings offer more revealing insights into the current state of AI discourse than into any language model's actual "state of mind."