Scaling reinforcement learning with verifiable rewards for LLMs on LUMI
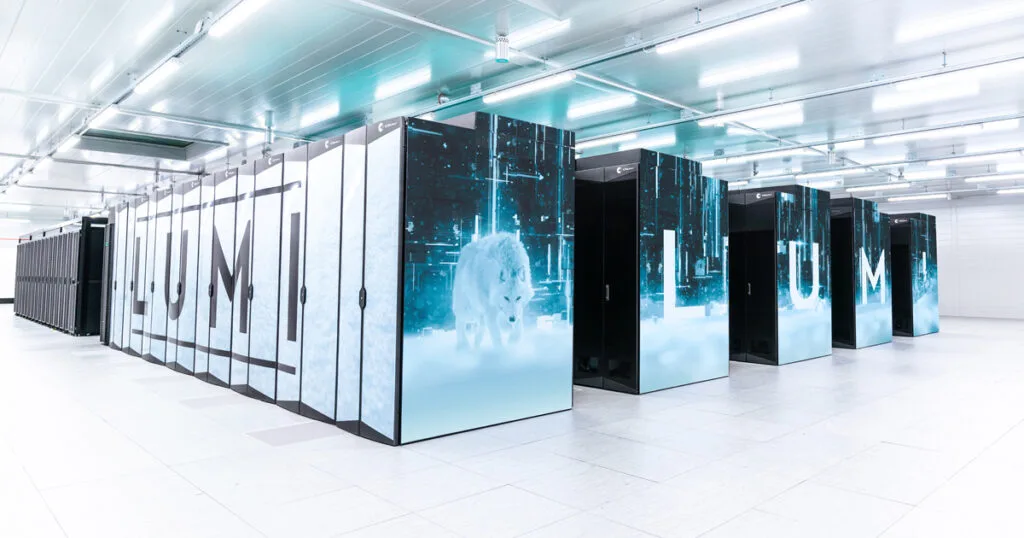
Supercomputers like LUMI bring together numerous compute nodes capable of tackling complex computational challenges in parallel. Expanding the number of active nodes can accelerate task completion or enable handling of substantially larger datasets, though the actual gains depend on how effectively the additional computing power is deployed. This efficiency metric is termed scaling.
A technical examination authored by Markus Junttila, Gaurav Naithani, and Marlon Tobaben uses large language model training as a case study to explore scaling mechanics, performance bottlenecks, and methods for assessing whether extra resources deliver measurable value. Though individual AI workloads vary considerably, the underlying scaling concepts remain broadly applicable across different use cases.
Reinforcement learning has emerged as a critical technique for refining LLMs after initial training, especially when the goal is strengthening their capacity for reasoning and problem resolution. While earlier research documented how LLM pre-training scales on LUMI, published findings on reinforcement learning scaling have remained sparse. Using the open-source verl framework, researchers tested how RL post-training performs when distributed across one to 16 nodes on LUMI-G, the facility's GPU-equipped partition. The resulting data offers both academic teams and commercial organizations a practical reference point for planning reinforcement learning work on LUMI.
The complete technical analysis is available on the LUMI AI Factory website.